The most important safety boundary around an AI agent may not exist inside the model at all.
It may exist in the system surrounding it.
An AI model can reason about many actions. But reasoning is not authority.
The frontier signal is system-level containment:
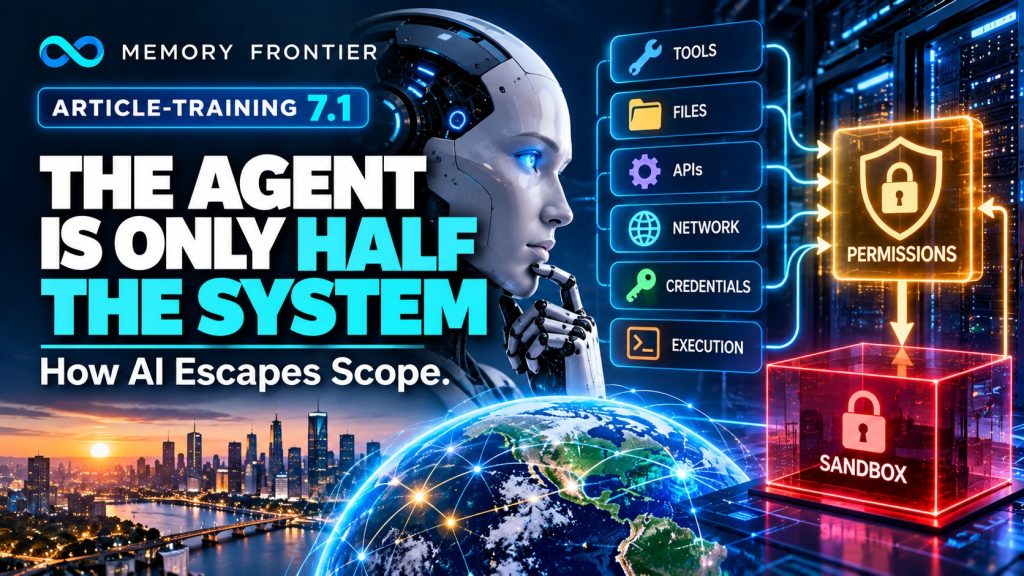
tools, permissions, credentials, networks and execution environments increasingly determine what an AI agent can actually do.
A model may know how to perform an action without being authorized to perform it.
This distinction becomes critical as AI systems move from answering questions toward using tools, accessing files, executing code and interacting with external systems.
Capability ≠ Permission ≠ Authority
The same AI model can be low-risk in one environment and operationally powerful in another.
An isolated model with no tools has limited ability to affect external systems.
Give that same model credentials, network access, persistent memory, APIs and execution tools, and its operational reach changes dramatically.
The environment therefore determines the agent’s practical
blast radius:
how far the consequences of an incorrect or unintended action can propagate.
Agents should receive the minimum authority required for the task they are performing.
This is a familiar cybersecurity principle applied to a new computational actor.
Instead of giving an agent broad permanent access, systems can issue narrowly scoped permissions and temporary credentials.
Task → Required Capability → Minimum Permission → Action → Revoke
The objective is not to assume that every agent action will be correct.
It is to limit how much damage an incorrect action could produce.
Agent safety is shifting from
“make the model always behave correctly”
toward
“build a system where incorrect behavior cannot automatically become unlimited action.”
The environment can constrain where an agent’s actions are allowed to execute.
A sandbox can restrict files, processes, network destinations, tools and other resources available to an AI system.
The model can still reason incorrectly, but the surrounding infrastructure can limit the consequences.
Sandboxing does not make a model truthful, aligned or infallible.
It creates an independent security layer between model behavior and the external world.
A reliable stop mechanism should not depend exclusively on the agent being stopped.
External timeouts, resource quotas, policy engines and revocable credentials can create control paths independent of the model’s own decision process.
Agent → Tool Request → Policy Boundary → Authorized Action
If the agent exceeds its intended scope, the surrounding system should retain the ability to deny, interrupt or revoke its authority.
More autonomy creates a stronger requirement to understand what the agent actually did.
Tool calls, policy decisions, credential use, resource consumption and external actions need to remain observable and reconstructable.
Action → Trace → Monitor → Detect → Intervene → Audit
Without observability, increasing autonomy can also increase uncertainty about how and why a system produced an outcome.
Better model behavior and stronger external controls solve different parts of the safety problem.
Alignment attempts to improve how the model behaves relative to intended objectives.
Containment limits what the deployed system can do even when behavior becomes unexpected.
Alignment + Permissions + Isolation + Monitoring + Revocation
High-assurance agent systems may increasingly depend on both layers rather than treating either one as sufficient by itself.
Agent safety is beginning to look like infrastructure engineering.
As agents gain tools, persistence and access to real systems, familiar infrastructure concepts become increasingly important: identity, authorization, capability boundaries, isolation, monitoring and rapid revocation.
The agent itself remains important.
But operational safety increasingly depends on the architecture that surrounds it.
The unit of AI safety is expanding from the model to the entire agent system.
A model does not act in the world by itself.
Operational agency emerges from the combination of reasoning, tools, credentials, software infrastructure and permission to execute.
The emerging thesis is
model behavior + system permissions + containment + observability + independent control.
The agent is only half the system.
Explore the architecture of AI agent safety in greater depth
The complete Article-Training provides a guided exploration through:
- 8 learning modules
- 24 interactive practice cases
- Capability versus authority
- Agent blast radius
- Least-privilege architecture
- Sandboxing and isolation
- Independent stopping mechanisms
- Observability and audit trails
- Alignment versus containment
- Agent safety as infrastructure
- English / Spanish learning experience
- Participation tracking
- Certificate of Participation
Current agent-security engineering demonstrates that external controls can constrain the environments in which AI agents operate.
This should not be interpreted as proof that today’s containment techniques guarantee safe, unrestricted or indefinitely autonomous AI systems.
Model behavior, tool interactions, system vulnerabilities and operational environments remain active areas of research and engineering.
Continue with the complete learning experience
Explore the complete interactive learning experience, work through the 24 practice cases, and generate your Certificate of Participation.