Drug discovery is entering a different computational scale.
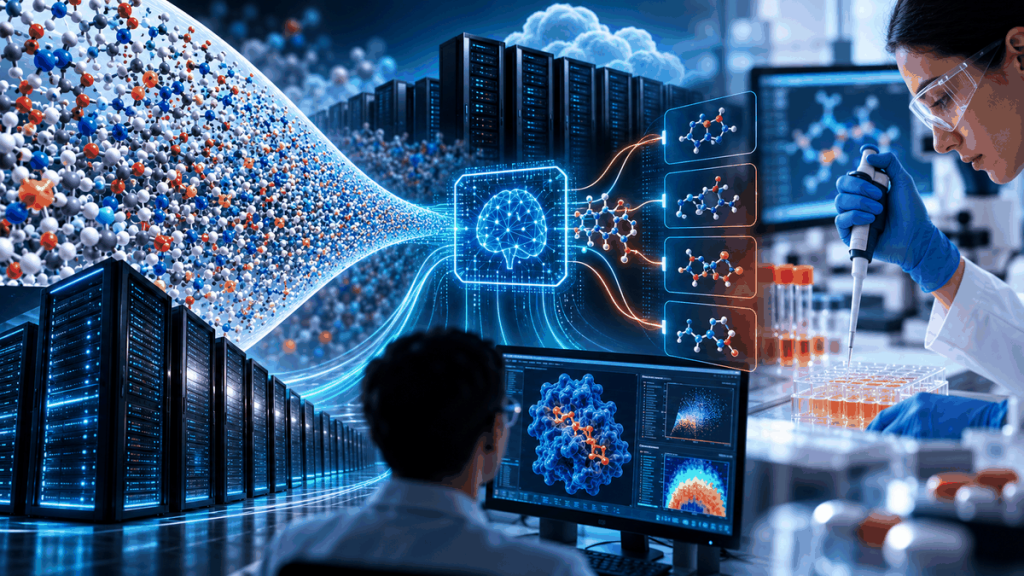
The possible chemical space is enormous. Even when billions of candidate molecules can be represented digitally,
experimentally testing every candidate is impossible.
How do we search an enormous chemical space efficiently enough to find the few molecules worth investigating?
AdaptiveFlow provides an important example of how artificial intelligence, molecular docking,
active learning, and large-scale computing can work together to attack that problem.
A molecular library is not automatically a discovery.
The Enamine REAL Space used in the AdaptiveFlow work contains approximately
69 billion screening-ready drug-like molecules.
That scale creates extraordinary opportunity — and an equally large computational bottleneck.
The challenge therefore changes from asking how many molecules can be collected to asking
how intelligently we can decide which molecules deserve deeper computation.
The goal is not simply to calculate faster. It is to avoid expensive computation where it is least useful.
AdaptiveFlow combines multiple computational techniques rather than depending on a single model.
- Molecular libraries
- Docking protocols
- Machine learning
- GPU acceleration
- Active learning
- Cloud computing
- Iterative candidate selection
Machine learning can help identify promising regions of chemical space, allowing computational resources
to become progressively concentrated on candidates that appear more useful.
Search becomes guided rather than brute-force.
Chemical Space → Sample → Dock → Learn → Prioritize → Search Again → Experimentally Validate
The system does not need to treat every candidate equally.
Results from one stage can inform what should be examined next.
At ultralarge scale, drug-discovery computation becomes a systems problem.
AdaptiveFlow includes more than 1,500 docking protocols and was designed to operate across very large cloud-computing environments.
The published work reports scaling to as many as 5.6 million virtual CPUs.
Software orchestration, data movement, compute scheduling, model selection, docking, storage,
and experimental follow-up must operate as parts of one integrated system.
The deeper shift is from computing more candidates toward
building discovery systems that learn what should be computed and tested next.
A virtual-screening result becomes scientifically stronger when it confronts physical evidence.
In the AdaptiveFlow study, selected candidates were experimentally tested, and the researchers reported
nanomolar inhibitors for targets including FSP1 and PARP1.
Prediction → Prioritization → Synthesis → Experiment → Measurement → Learning
That experimental step transforms the workflow from purely computational ranking into a closed loop
connecting digital prediction with laboratory evidence.
Promising activity is only an early stage of drug discovery.
A candidate may still face challenges involving:
- Selectivity
- Toxicity
- Absorption
- Distribution
- Metabolism
- Stability
- Dosage
- Manufacturing
- Preclinical validation
- Clinical trials
A successful virtual-screening result can identify promising starting points.
It does not establish that a safe and effective medicine has been created.
AI can help decide where expensive scientific attention should be concentrated.
Large Search Space → Intelligent Prioritization → Expensive Evaluation → Evidence → Updated Search
This is a general pattern for AI-assisted science: use learning systems to decide what should be examined next.
Scientific opportunity can grow faster than our ability to examine it.
Adaptive computational systems provide one possible response.
Instead of asking computers to evaluate everything equally, researchers can create systems that learn where to search next.
The frontier therefore moves from computing more candidates
toward closed-loop discovery systems that decide what should be computed and tested next.
Explore AdaptiveFlow and ultralarge molecular search in greater depth
The complete Article-Training provides a guided exploration through:
- Learning modules
- 12 interactive practice cases
- Virtual-screening scenarios
- AI-assisted discovery concepts
- Evidence-boundary exercises
- Critical-thinking exercises
- English / Spanish learning experience
- Participation tracking
- Research grounding
- Certificate of Participation
AdaptiveFlow demonstrates a powerful computational approach for searching ultralarge molecular spaces
and prioritizing candidates for experimental investigation. The reported experimental validation strengthens
the scientific significance of the workflow, but discovery-stage inhibitors are not equivalent to approved medicines.
Safety, efficacy, pharmacology, manufacturability, preclinical studies, and clinical trials remain separate and demanding stages.
Continue with the complete learning experience
Explore the complete interactive learning experience, work through the 12 practice cases,
and generate your Certificate of Participation.