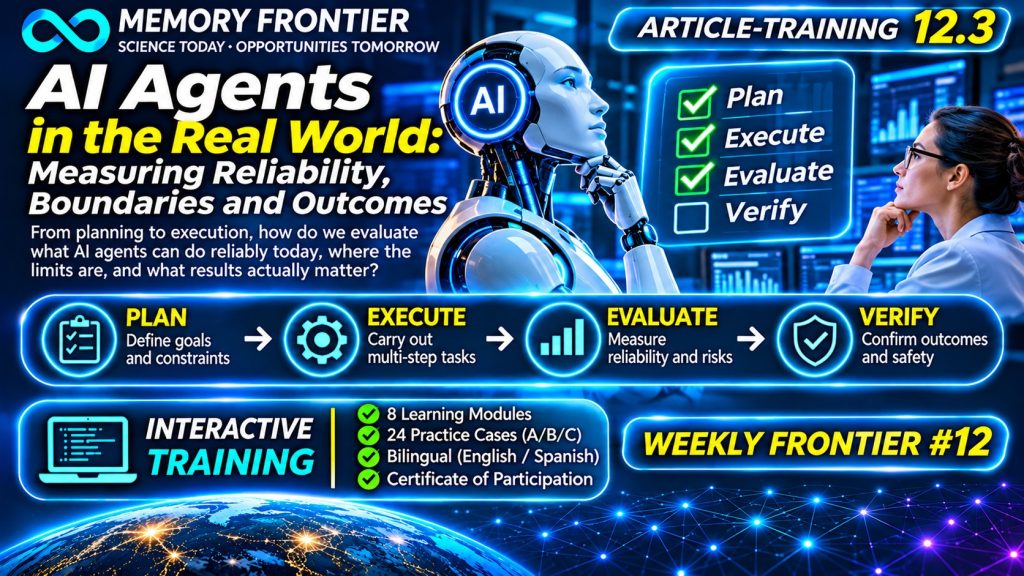
🤖 AI Agents in the Real World: Measuring Reliability, Boundaries and Outcomes
When does an AI agent move beyond an impressive demonstration to dependable real-world execution?
AI agents can combine language models, tools and multi-step workflows to perform tasks. Their value depends on verifiable completion, constrained permissions, recovery from failure and measurable outcomes—not on the appearance of autonomy alone.
From chat to action
Agents may plan, reason and call external tools, but a plausible response is not proof that an action was completed. Verify the actual external state and the intended outcome.
Defining success criteria
Before deployment, specify the task boundary, permitted actions, success metrics, deadlines and failure conditions. An evaluation should test completed workflows, not merely convincing intermediate messages.
Tool permissions and boundaries
Grant only the permissions needed for a defined task. Separate reading information, proposing a change and executing a consequential action. Use explicit authorization and least-privilege access.
Observability and traceability
Capture tool calls, timestamps, approvals, outcomes and error conditions in an auditable record, while protecting confidential data. Logs help distinguish claimed actions from verified ones.
Failure handling and recovery
Test timeouts, incorrect tool outputs, duplicate actions and unexpected changes. Define stop conditions, escalation paths and safe rollback when possible; some actions cannot be reversed.
Human oversight
Keep human review for high-impact, irreversible or financially consequential actions. The agent should know when to stop and request authorization rather than silently expanding its scope.
Evaluation beyond demos
Use held-out real-world tasks and repeated runs. Measure end-to-end completion, severity of errors, intervention frequency, latency and cost. Single successful demonstrations do not establish dependable performance.
Incubation: verifiable agent operations
An incubator opportunity is an observe–plan–act–verify workflow with bounded permissions, audit logs, exception handling and independently checked business outcomes. Commercial value remains a hypothesis until measured.
A successful benchmark or polished agent demo does not prove safe, reliable deployment. Reliability depends on task distribution, permissions, monitoring, failure severity and independent end-to-end evaluation. Forecasts about fully autonomous operations are projections, not established results.
Go deeper: 8 modules · 24 practices
Explore the full English/Spanish interactive training, check your understanding, and unlock the Certificate of Participation after 50% participation.
https://hiapromo.com/frontier/12.3.-AI_Agents_in_the_Real_World_Measuring_Reliability_Boundaries_and_Outcomes.html
Editorial note: Educational synthesis of agent evaluation and operational safety principles. Verify primary studies, test conditions and publication dates before treating specific agent-performance claims as established. Real-world deployment requires independent testing.